
Reddit Scraper – Extract Posts, Comments & Users
RedScraper is a no-code Reddit scraper for posts, comments, subreddits, and user profiles. Configure filters and fields in the dashboard or API, export JSON, CSV, XML, or Excel — billed on successful compute time, not failed runs.
- High-Speed Scraping
- No-Code Automation
- Export to CSV, JSON, Excel & XML
What is a Reddit scraper?
A Reddit scraper collects publicly visible posts, comments, communities, and profiles into structured files you can filter, export, and analyze. People sometimes type it as “reddit scrapper,” but the product is the same idea: turn Reddit discussions into clean CSV, JSON, XML, or Excel — without writing your own crawler.
RedScraper is that Reddit scraper as a managed service: you pick a search query or Reddit URL, choose entity types and fields, and get normalized records for analytics or automation. Jobs run in our environment, so you do not operate headless browsers, proxies, or rate-limit logic yourself. The same task model works in the dashboard and over the HTTP API, with filters for sort, time windows, NSFW, and up to 10,000 items per configuration.
Start with a dedicated flow when you already know the entity: post scraper, comment scraper, user scraper, or subreddit scraper.
Ways to specify a target
- Keyword search across Reddit — see query syntax examples.
- Direct Reddit URLs (subreddit listing, post thread, user profile, comment permalink, or feeds such as /r/popular/) — URL patterns.
- Advanced task parameters: field selection, sort, time filters, limits, NSFW, and export encoding — configuration reference.
Entity types you can materialize
- Posts — title, body, scores, media, flair, permalink; see post field list.
- Subreddits — metadata, subscriber counts, rules, moderators; see community fields.
- Comments — text, scores, reply counts, thread URLs; see comment fields.
- Users — karma splits, avatar, NSFW flags, profile copy; see user fields.
Usage is metered in wall-clock compute time for successfully completed task executions. There is no separate quota on row volume: within a finished job you can pull as many matching records as the task parameters allow. Failed or incomplete runs do not debit your balance.
Compute time and billing model
Plans include a monthly pool of execution hours. Metering starts when a task begins processing and stops when results are delivered (or the job terminates cleanly). This aligns cost with actual workload rather than with arbitrary export row counts.
- Success-only charging: failed, throttled, or aborted requests do not consume compute balance.
- Processing-based measurement: billing reflects server-side extraction and normalization time, not idle queue time in the UI.
- Unbounded output per successful job: within a single completed execution, data volume is constrained only by your configured limits and Reddit-side availability, not by a separate “rows purchased” tier.
Current list prices and included hours are shown on the Pricing page.
Run your first Reddit scrape
Create a task in the dashboard or call the API. You are billed only for successful execution time, not failed runs.
End-to-end execution pipeline
Whether you trigger a scrape from the UI or the API, the pipeline is the same: validate inputs, enqueue work, fetch and normalize Reddit entities, then emit a dataset in your selected interchange format.
1. Authenticate
Create an account to obtain dashboard access and API credentials tied to your workspace.
2. Declare the source
Supply either a keyword query or a concrete Reddit URL that resolves to a feed, post, user, or comment tree.
3. Apply filters and projections
Choose sort mode (where applicable), time range for search-backed post queries, NSFW policy, max items, and which fields to include in the export.
4. Execute the task
Run the job; only successful executions decrement compute hours. Partial failures are surfaced in the run history.
5. Download structured output
Retrieve JSON, CSV, XML, or Excel for ingestion into BI tools, notebooks, or your own ETL.
Inputs, query grammar, and runtime options
Keyword-driven discovery
Reddit's search index is addressed with plain text. Multi-token queries narrow recall; quoted phrases enforce literal spans; combined tokens approximate boolean AND semantics at the search-engine level.
- Single token (broad recall)
gaming - Multiple tokens (tighter intent)
gaming laptop - Quoted phrase (literal match)
"best gaming laptop" - Composite query (brand + issue class)
iPhone battery issue - Temporal monitoring stub
AI tools 2026
URL-backed extraction
When you already know the canonical resource, pass the HTTPS permalink. The scraper resolves the resource type (subreddit, post, comment, or user) and expands the appropriate subgraph.
- Subreddit listing
https://www.reddit.com/r/technology/ - Post with comment tree
https://www.reddit.com/r/technology/comments/abc123/example_post/ - User profile
https://www.reddit.com/user/username/ - Deep comment permalink
https://www.reddit.com/r/technology/comments/abc123/example_post/def456 - Aggregate feeds
https://www.reddit.com/r/popular/
Task parameters that affect results
These knobs are orthogonal to “keyword vs URL”: they control ranking, freshness, volume, safety filters, and serialization format.
- Sort: none (default), hot, top, new, or relevance for applicable surfaces. Hot is defined for post listings only.
- Time window: restricts post age when the upstream source is search-based (hour through year buckets).
- Limit: integer cap between 1 and 10,000 collected items; higher values increase runtime and compute consumption.
- NSFW: global toggle applied across posts, comments, users, and subreddit metadata.
- Serialization: JSON, CSV, XML, or Excel for downstream compatibility.
Run your first Reddit scrape
Create a task in the dashboard or call the API. You are billed only for successful execution time, not failed runs.
Field-level schema reference
The dashboard lets you toggle individual columns per entity. Omitting unused fields reduces noise and can shorten processing for wide subgraphs.
Post entity
Captures the submission record: textual content, engagement signals, subreddit linkage, media attachments, and moderation-facing flags.
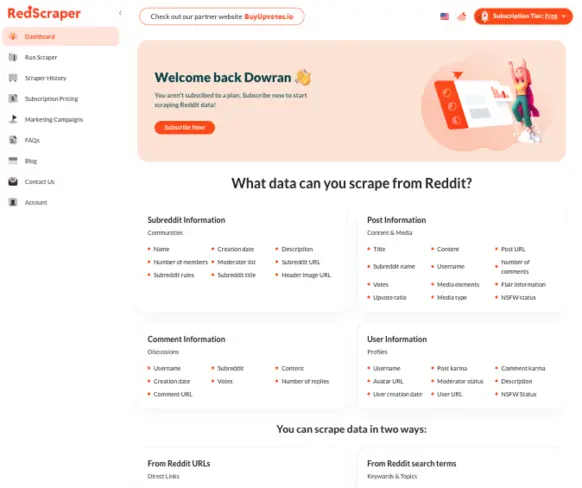
Available fields: title, body, post URL, subreddit name, author username, score, upvote ratio, comment count, media references, media type classification, flair text, NSFW boolean.
Subreddit (community) entity
Describes the community object: descriptive copy, subscriber scale, ruleset text, and visual branding assets.
Available fields: name, created timestamp, public description, subscriber count, moderator list, canonical URL, rules markdown, display title, header image URL.
User profile entity
Surfaces public profile signals Reddit exposes on user pages, split by contribution type where karma is reported separately.
Available fields: username, post karma, comment karma, avatar URL, moderator flag, bio/description, account creation date, profile URL, NSFW flag.
Operational guide: how to scrape Reddit users.
One Reddit scraper for posts, comments, users & communities
RedScraper is a no-code Reddit scraper: pull discussions, user activity, and community metadata into exportable datasets — then open a specialized scraper page when you need a deeper field list.
Comments Analysis
Reddit Comment Data Extractor
Access full Reddit comment threads with nested replies, timestamps, and engagement metrics. Explore discussions and identify trends.
Collect comments by keyword, URL, or subreddit and export structured datasets.
Scrape full comment trees
Filter by keyword or author
Collect historical discussions
User Profile Analysis
Reddit User Profile Data Extractor
Access public Reddit user profile data, including karma, activity, and subreddit participation.
Analyze user behavior, engagement, and activity patterns with structured datasets.
Reddit user profile information extraction
Scrape public profiles
Track posts and comments
Analyze karma trends
Export user datasets
Community Tracking
Subreddit Data Extraction Tool
Access subreddit data, including rules, moderators, activity, and engagement metrics.
Analyze trends and build structured datasets.
Monitor community activity
Track growth trends
Analyze moderation data
Export subreddit datasets
Content Scraping
Reddit Post Data Extractor
Access Reddit post data, including titles, content, images, and engagement metrics.
Build structured datasets for analysis.
Scrape posts by keyword
Extract images and media
Track engagement metrics
Export post datasets
Who uses this Reddit scraper?
Marketers, researchers, and analysts use RedScraper as their Reddit scraper to monitor discussions, export clean datasets, and study real user behavior — without building a crawler in-house.
Marketing & Growth Teams
Use the Reddit scraper to track brand and competitor mentions, sentiment, and emerging threads in real time.
Content & SEO Specialists
Pull real questions and phrasing from Reddit threads to fuel topic ideas, FAQs, and long-tail keyword research.
Product & UX Teams
Collect honest feedback about features, bugs, and usability from public Reddit discussions.
Researchers & Analysts
Export large Reddit datasets for behavioral and sentiment analysis across communities at scale.
Built for people who need Reddit data, not screenshots
How this Reddit scraper works
Configure a Reddit scraper task in a few steps — no setup scripts, no Reddit API keys required.
Create Your Free Account
Sign up and access our Reddit scraping dashboard in seconds.
Enter Subreddit, Keyword, or URL
Choose any subreddit, post URL, or keyword to collect relevant Reddit data.
Start Reddit Data Scraping
Our scraper extracts posts, comments, users, and metadata automatically.
Download Clean Data Files
Export Reddit data to CSV, JSON, Excel, or XML for analysis.
What a Reddit scraper exports
Build custom datasets from posts, comments, subreddits, and user profiles. RedScraper is an all-in-one Reddit scraper — pick an entity below for field details.
Clean, structured Reddit data — ready for exportPosts
Structured datasetTitle
Content
Author
Subreddit
Upvotes
Comments count
+ more…
Comments
Structured datasetAuthor
Content
Post URL
Subreddit
+ more…
Subreddits
Structured datasetName
Description
Members count
Rules
Moderators
+ more…
Users
Structured datasetUsername
Post karma
Comment karma
+ more…
Reddit scraper pricing
Basic
$50
per month
Unlimited data output
10 hours of compute time
Compute time is only counted when your scraping requests are successful. Failed requests don't use your time allowance.
Professional
$100
per month
Unlimited data output
50 hours of compute time
Perfect for medium-scale operations. Get 5x more compute time to handle larger scraping projects with ease.
Enterprise
$150
per month
Unlimited data output
100 hours of compute time
Built for large-scale operations. Maximum compute allowance for extensive data collection and analysis projects.
Frequently Asked Questions
What is a Reddit scraper, and how does RedScraper work?
A Reddit scraper turns public Reddit posts, comments, communities, and profiles into structured data. RedScraper is a managed Reddit scraper: you configure tasks (keyword search or Reddit URLs), choose fields, and download normalized datasets. We meter successful execution time — no DIY browsers or Reddit API quotas.
What kind of data can I scrape with RedScraper?
You can materialize posts, comments, subreddit metadata, and user profiles with selectable columns (titles, bodies, scores, permalinks, flair, media references, rules, moderators, karma splits, and more). Output ships as JSON, CSV, XML, or Excel.
Do you support historical Reddit data?
Yes, within what Reddit exposes for a given resource. Search-backed tasks support time-window filters (for example last day through last year) on post results; permalink-based tasks return the current thread state available at fetch time.
Can I scrape Reddit without coding or technical skills?
Yes. The dashboard is no-code. The same task model is also available over HTTP for engineers who want to automate runs without operating their own scrapers.
Can I access Redscraper via API?
Yes. You can create and monitor scraping tasks programmatically and download structured results into your own pipelines, in addition to using the browser UI.
Can I filter by keywords, URLs, dates, and NSFW?
Yes. Use keywords or canonical Reddit URLs as the source, then apply sort modes where supported, time filters for search-based post queries, per-task item limits (up to 10,000), and an NSFW include/exclude toggle.
How does Reddit user profile data extraction work?
User tasks resolve public profile pages into structured fields (for example karma breakdown, avatar URL, NSFW flag, description, creation date). For a step-by-step guide, see our documentation on scraping Reddit users.
Do I need the Reddit API to use RedScraper?
No. RedScraper does not require Reddit API keys or OAuth developer apps; collection runs through Redscraper’s execution environment.
Is it legal and safe to use RedScraper?
RedScraper is designed to collect publicly visible Reddit content only. You remain responsible for complying with applicable laws and Reddit’s terms for how you use exported data.
Is there a limit to how much data I can scrape?
Per task you can configure up to 10,000 items. Monthly usage is gated by your plan’s included compute hours; successful jobs may return large row counts without a separate “row limit” SKU.
Comment entity
Flattened comment rows include engagement metrics and a stable permalink for re-fetch or graph reconstruction.
Available fields: author, subreddit, body, created timestamp, score, direct reply count, comment permalink.